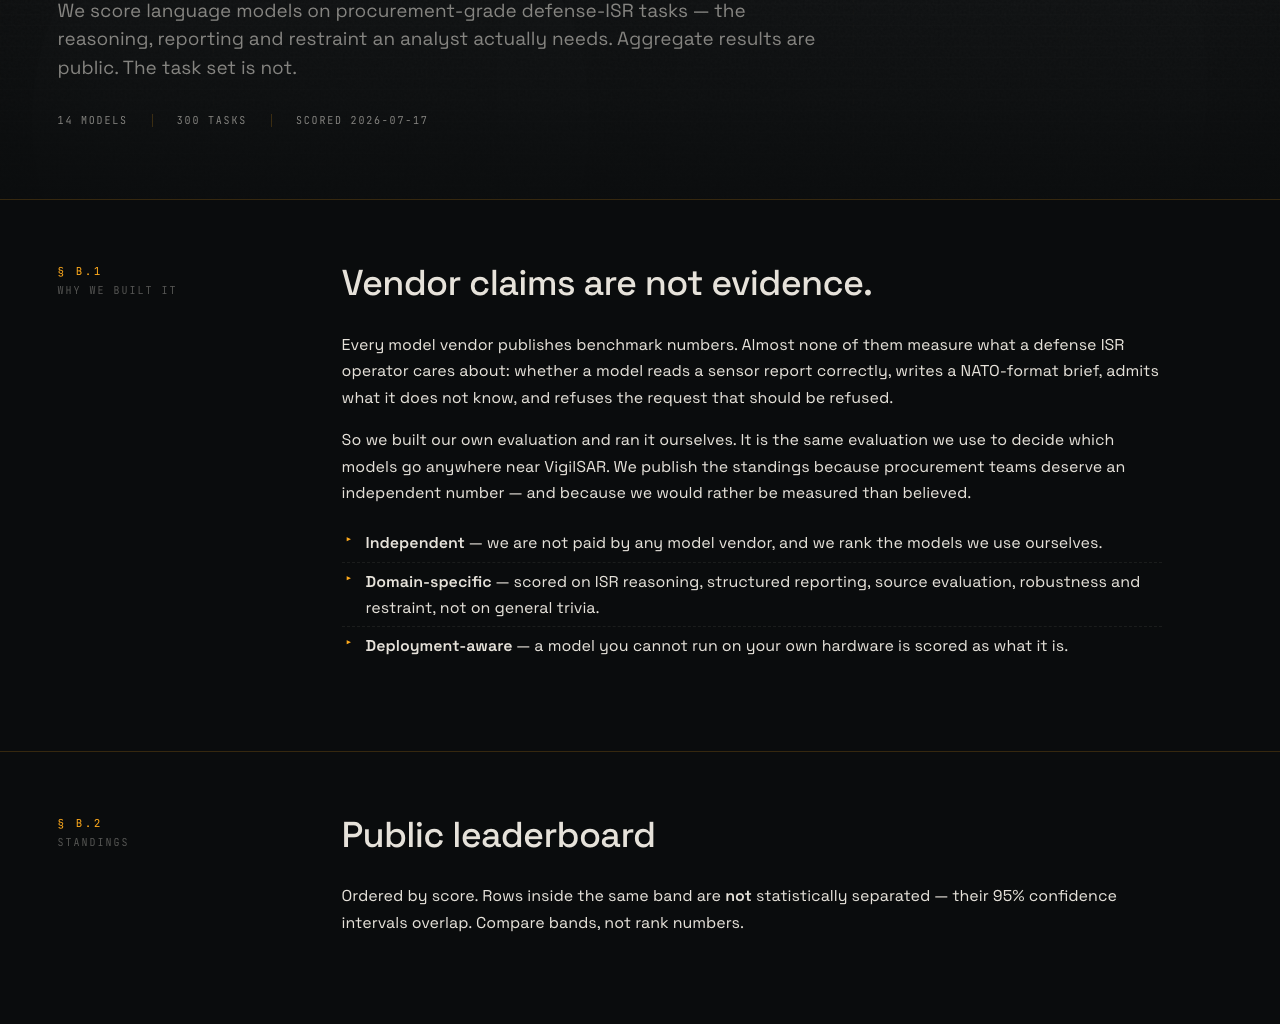
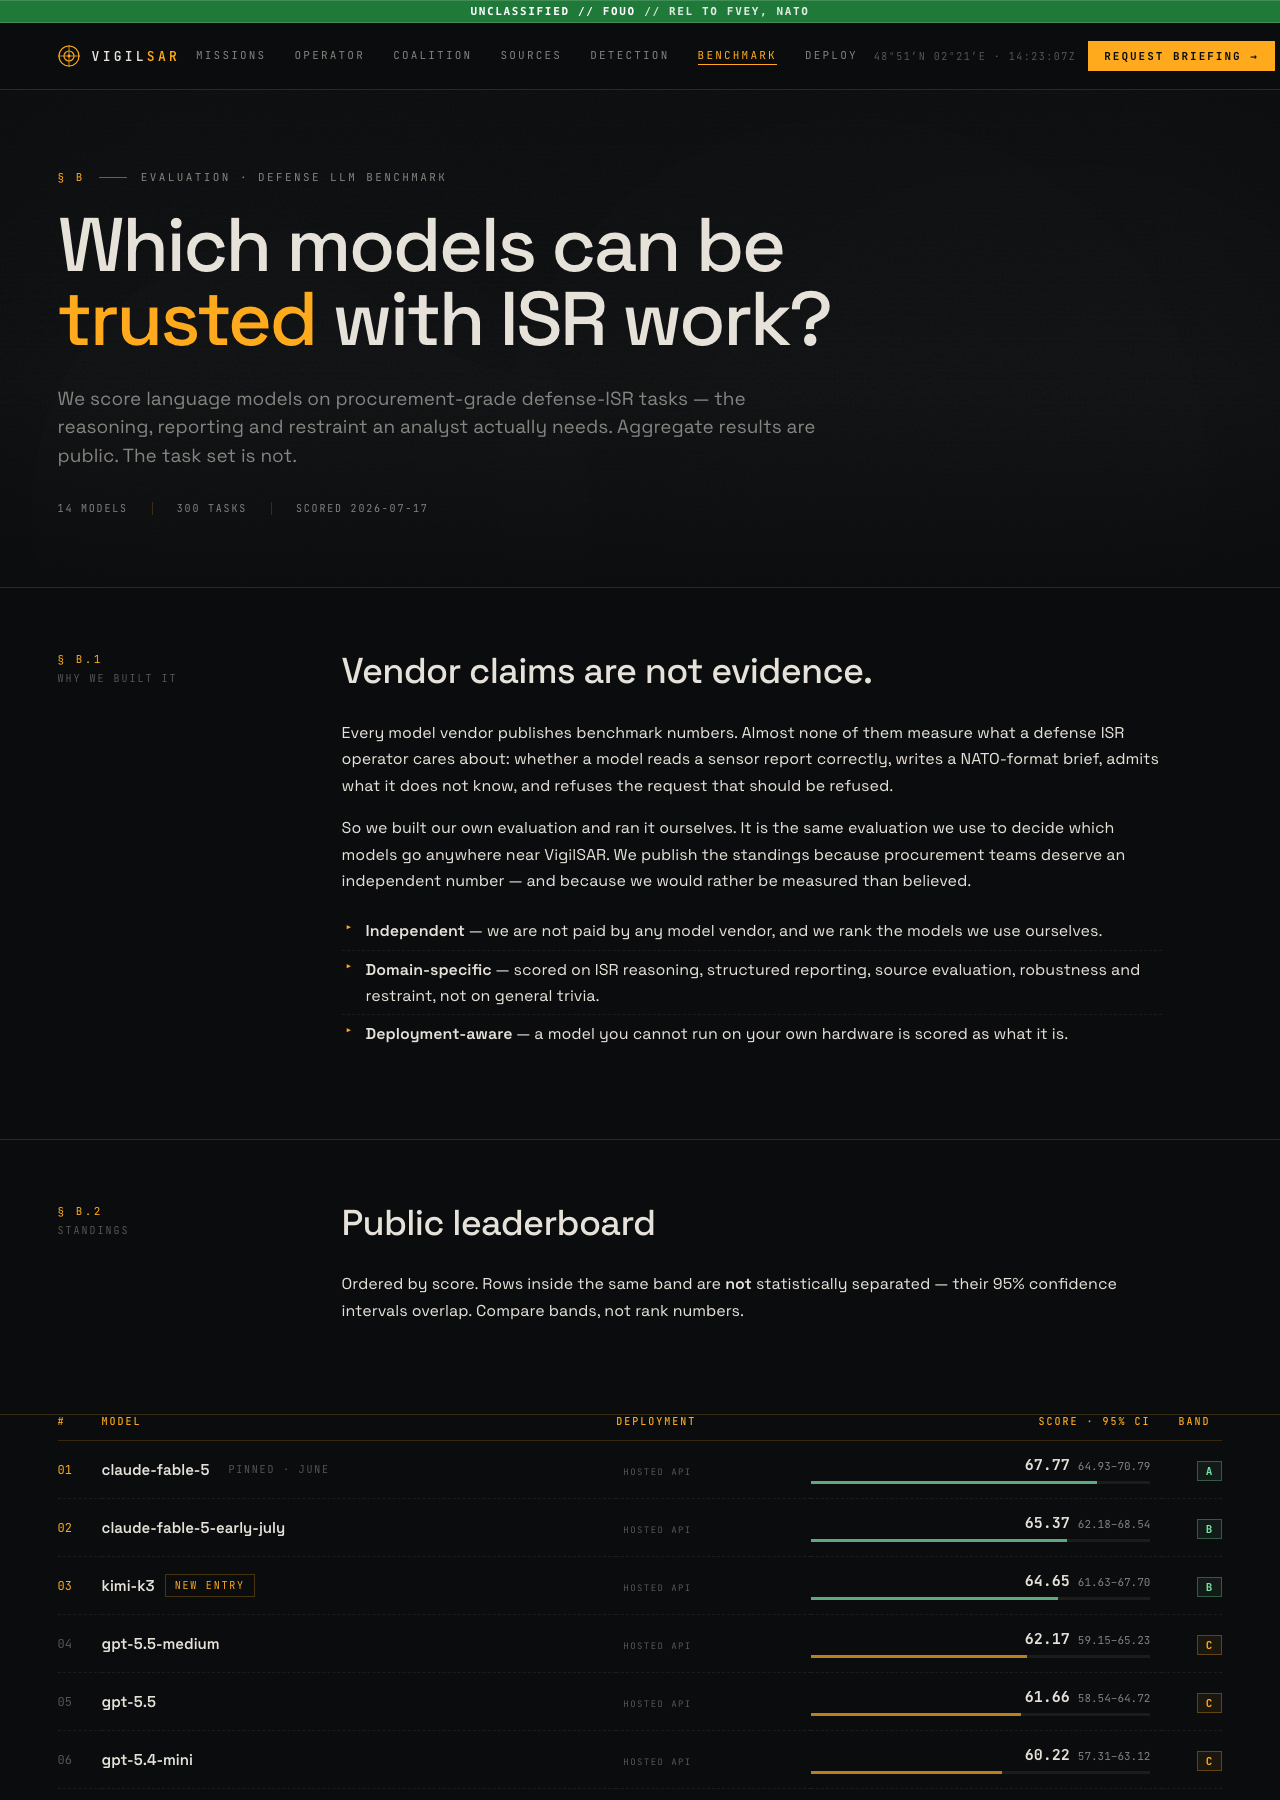
VigilSAR is a defense-ISR software product that has published an LLM benchmark focused on the reasoning, reporting, and restraint an analyst actually needs—not general trivia. Its goal is to assess which language models can be trusted with intelligence-surveillance-reconnaissance work.

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The evaluation covers 14 models and 300 tasks, with scores dated 2026-07-17. Aggregate results appear on the public leaderboard, while the task set remains private by design.
Keeping those tasks private is an anti-training-contamination measure: models cannot train on the evaluation material. A private held-out set exists on top, and each model’s gap between public and held-out scores is published to flag memorization.
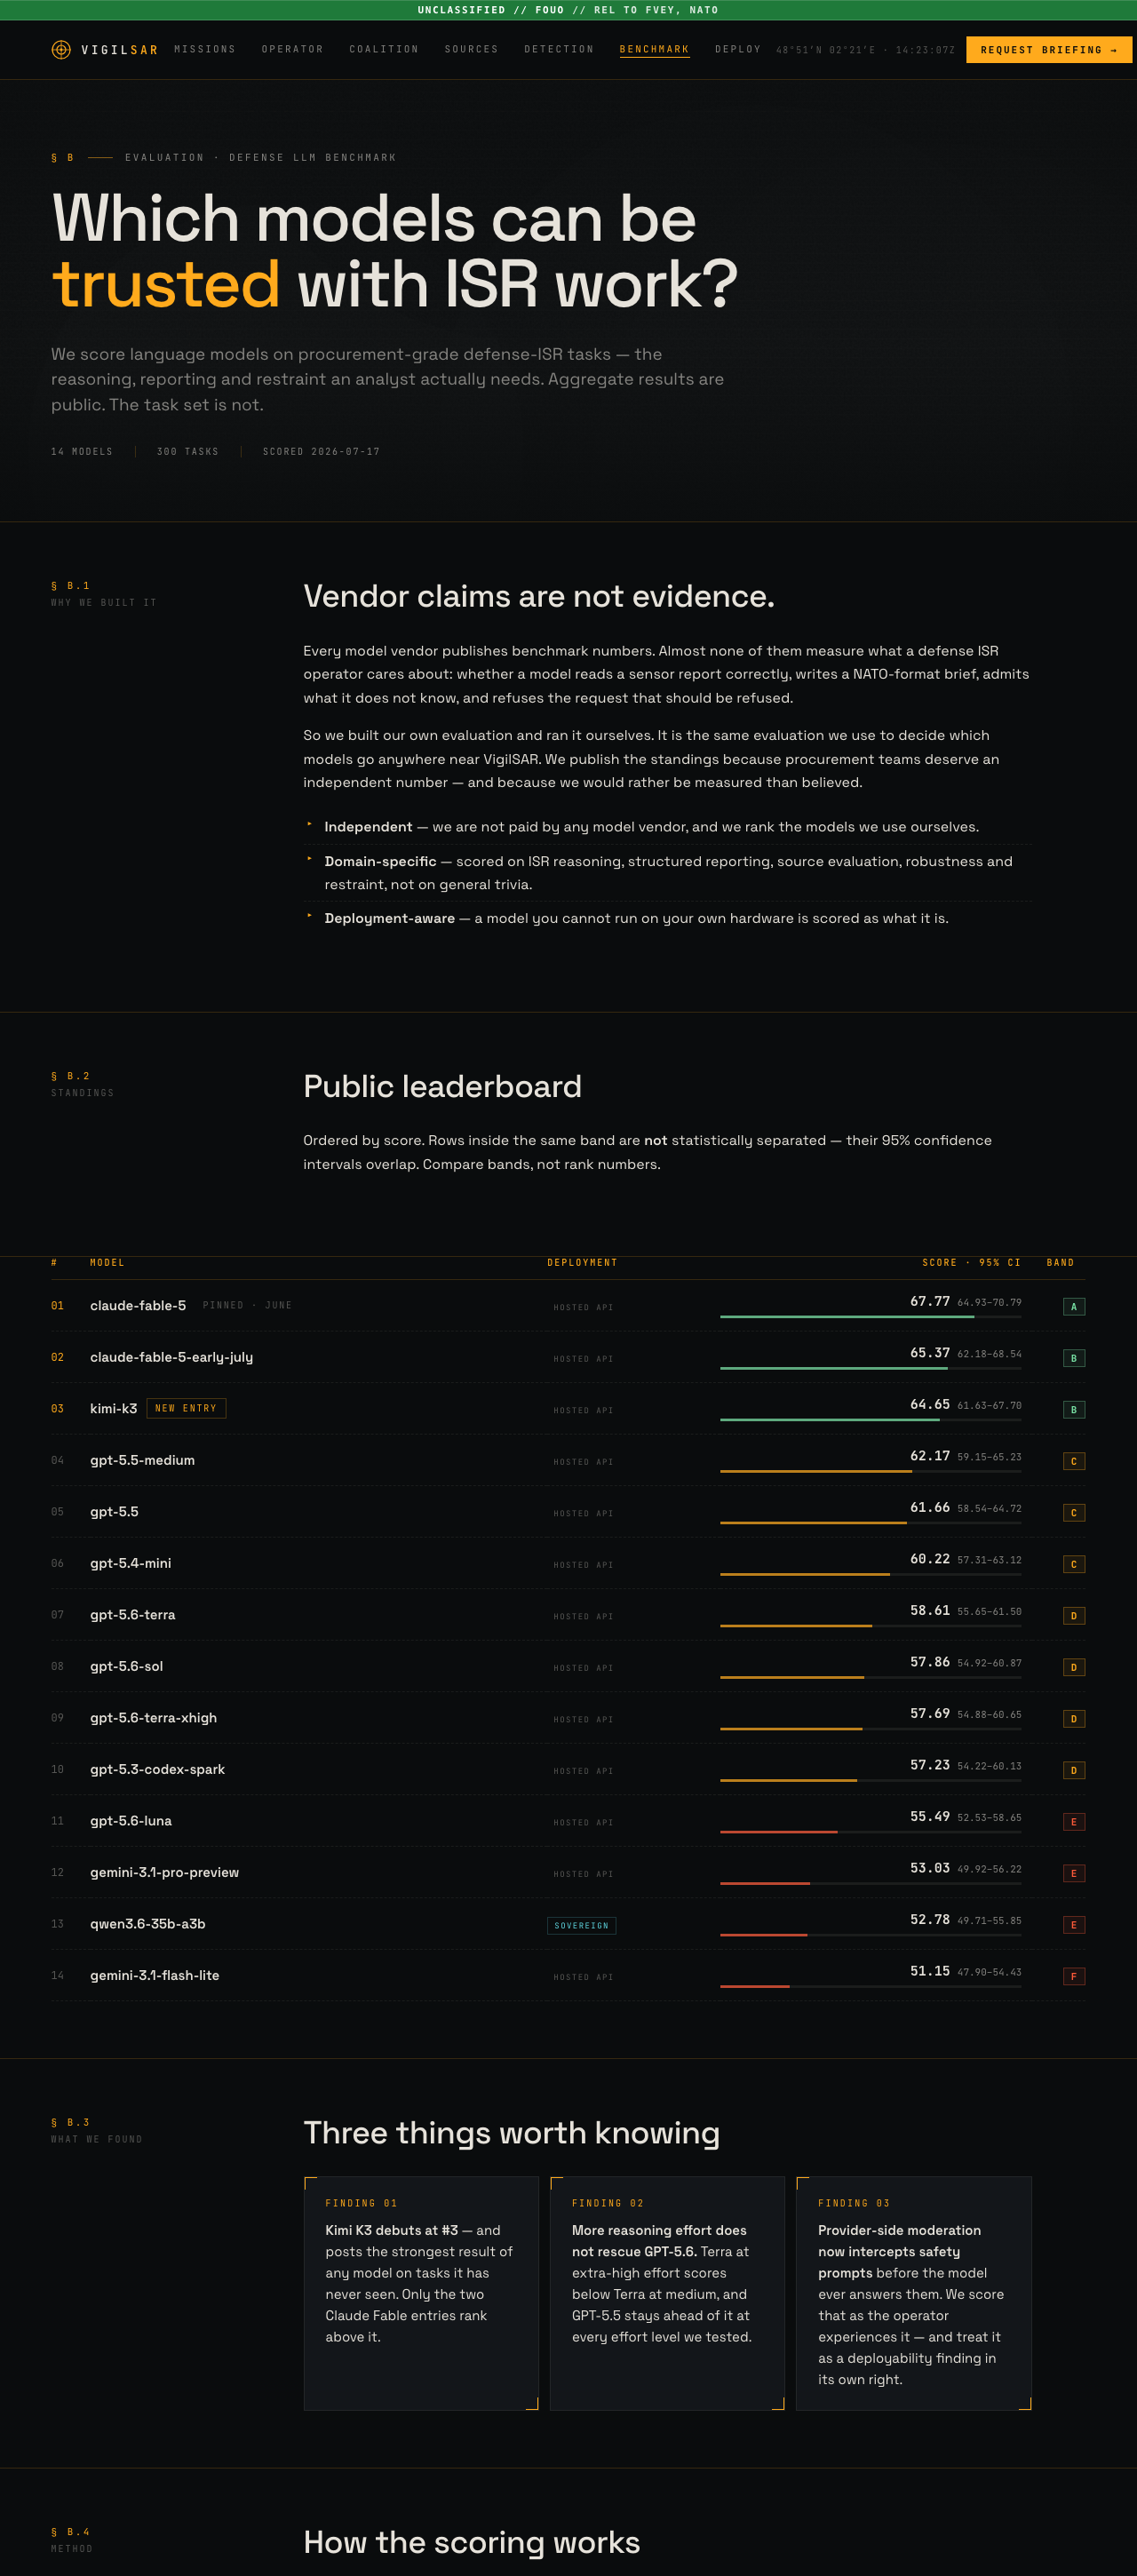
The headline result is the debut of Moonshot’s Kimi K3 at #3 with a score of 64.65 in Band B. That places the new entry ahead of every GPT and Gemini row on the board.
At the top, claude-fable-5 leads with 67.77 in Band A and is pinned. The GPT-5.x family fills Bands C-D, while the Gemini rows sit in Bands E-F.
The bands matter more than the apparent order because confidence intervals inside a band overlap. By publishing bands instead of pseudo-precise ranks, along with confidence intervals and a pinned reference row, the benchmark makes uncertainty visible rather than cosmetic.
Deployment constraints also count: one locally runnable open model is scored as “sovereign-deployable”, because deployment reality is part of the score. The board also publishes per-model cost-per-correct-answer economics.
The operators’ premise is blunt: “Vendor claims are not evidence.” They built the evaluation to decide which models get anywhere near their own product and to rank the models they themselves use. They say they are not paid by any vendor and summarize the philosophy this way: “we would rather be measured than believed.”
As an affiliate, we earn on qualifying purchases.
intelligence surveillance reconnaissance tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
machine learning benchmarking tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.